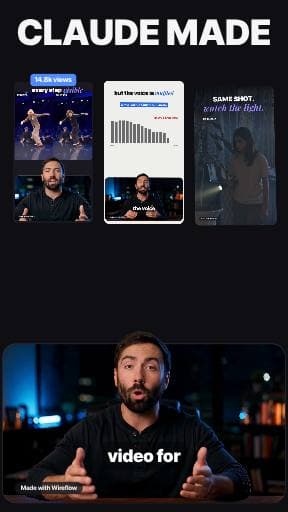
The board behind the "Claude made this video" reel. Kling 4.0 says each line from your start frame, Remove Pauses cuts every breath, ElevenLabs Voice Swap re-voices it in a clone of your real voice so the lips still match, and the Kallaway-style editor puts you in a 16:9 card under the graphics. Add your face refs, a start frame, 30 s of your voice and your script, then let Claude (via the Wireflow MCP) run it and show you frames before it renders.
Fork to your canvas makes a full copy in your account, every node and edge on a fresh canvas. Add to an existing workflow drops it into one of yours as a single collapsed node: its inputs become ports on the left and its outputs ports on the right, so you wire it like any other node.
Instructions
# READ FIRST · MASTER Talker Reel v3 (BENCHMARK, 10-31)

Every @mikeonai talking-head reel starts by FORKING this board. Michael, 10-31: "We cannot have regression. This is the benchmark." Skill: michael-reel. Gate: `node ~/Documents/wireflow-ads/michael-daily-avatar/reel-check.ts <forkId>` and paste its last line. Every output on this board is an EXAMPLE from the 10-30 "How a real swap works" reel.

## The standard (numbers)
- **Takes:** Kling 4.0 reference-to-video, 1080p NATIVE, 16:9, one take per script line, generated at the line's real length (3 to 30 s). Start frame = LOCKED PLATE v2 (neutral, lips closed). Identity refs = REF 1 (front) + REF 3 (3/4) only, never the smiling ref. @Voice1 = KLING VOICE made from VOICE SAMPLE (27 s of his real 09-30 recording).
- **Delivery direction in EVERY take prompt:** "a calm, matter-of-fact statement with a natural falling intonation on the last word, not a question, not drawn out, no sing-song", ONE emphasized word named, and "a brisk pace with no pauses between sentences". Voice Swap copies Kling's intonation exactly, so an odd inflection survives the swap. Fix it in the prompt, listen to every take's last words, re-roll an odd one.
- **Voice Swap:** VOICE SWAP Tn (audio:elevenlabs_voice_changer, eleven_multilingual_sts_v2) after EACH trim, into "Michael v2 (Snowball 09-30)" voice_id `TJDm0feGweaZxbMzu4yU`, set in config AND params. NEVER `FVfaC7GnHWbkCW6rO1ly` (the HeyGen-sample clone, a clone of a clone: "didn't sound like me"). Speech-to-speech keeps Kling's timing (0 ms offset). Why: Kling's own audio is band-limited (about 12 kHz; above 12 kHz it measures -43 dB vs -31 on the swap and on the raw mic).
- **Loudness:** TAKE AUDIO JOIN -> VOICE LOUDNESS MATCH (`va-match`, audio_master at -12.8 LUFS, the old Kling take level; the swap comes out about 5.6 dB quieter) -> the reel's audio AND Whisper. Without it the music bed jumps up under the voice.
- **Card geometry (Kallaway 16:9 window):** `popout-rim` 1040x585 at x0 y627 (96% of frame width, bottom anchored). `popout-room` and `popout` 1310x737 at x0 y621; room crop {x .103, y .112, w .794, h .794}; cutout crop {x .103, y 0, w .794, h .906}. Take zoom = 1310/1040 = 1.26x of the card (gate allows 1.0 to 1.3). Eyes stay INSIDE the card, about 12% of card height below its top; only hair breaks the edge. Adjust crop.y per take for the eye line.
- **Pacing:** 200+ words per minute and pauses (gaps over 250 ms, one deliberate hold over 2 s excluded) under 8% of runtime. Kallaway measures 221 to 238 WPM with 3.5 to 3.9% pauses. The 10-30 example on this board is 168 WPM with 25% pauses, so this board FAILS the pacing rule on purpose until Remove Pauses ships.
- **Finish:** no text over his face (punch-in words above or beside him; captions Inter Tight 800, 68 px, topPercent 89, below the chin), music bed about 12 dB under, whooshes on cuts, master -14 LUFS / -1.5 dBTP, end card held 3 s or more, lip sync under 40 ms at start, middle and end.
- **Never:** Sync Lipsync, a HeyGen line laid over a take, Rhea or any upscaler, Proteus, Starlight, bria, BiRefNet, the smiling ref, "cinematic" or energy words in a talker prompt.

## Swap per episode (nothing else)
1. **SCRIPT LINE T1..Tn:** the new lines (topic-research skill first, script graded A).
2. **TALKER PROMPT T1..Tn:** replace ONLY the quoted line and the emphasized word. Keep the start-frame, framing, delivery and realism wording. Set each take's duration to its line's real length.
3. **Graphics:** replace the EXAMPLE inputs (groups 6, 8, 9, 10) and the reel's `t_gfx` / `t_hero` clips. Keep the card tracks (`popout-rim`, `popout-room`, `popout`), `t_grain`, `t_pill`, the audio tracks and the caption style.
4. **TRIM Tn** start/end to each new take's speech; TAKE AUDIO JOIN `gaps` only for a deliberate hold.
5. **Keep as is:** LOCKED PLATE v2, REF 1, REF 3, VOICE SAMPLE, KLING VOICE, ROOM PLATE, the Voice Swap settings, the loudness match, the master.

## Order of operations
1. Fork. Preflight credits before every paid run: `npx tsx scripts/preflight-credits.ts <forkId> --node <take>`.
2. Hook take (T1) only. Michael looks. Then fan out T2..Tn.
3. Every take: listen to the last words, check for spelled-out or repeated lines, re-roll odd intonation.
4. Take -> [Remove Pauses, once #3524 ships] -> TRIM (CRF 12) -> VOICE SWAP into Michael v2 -> TAKE AUDIO JOIN.
5. MATTE (veed) on each trimmed 1080p take. ROOM PLATE stays pinned.
6. VOICE LOUDNESS MATCH -> WORD TIMINGS (Whisper) -> reel captions and beat cuts.
7. Edit the reel. Preview stills on every beat: card geometry, eyes inside the card, no text over his face.
8. Render -> MASTER -14 LUFS -> 6 fps contact sheet, lip-sync cross-correlation, IG-compressed check.
9. Run reel-check.ts on the fork and paste the last line. Show Michael ONE finished piece, sent inline.

## Remove Pauses (pending #3524)
Remove Pauses (`utility:remove_pauses`) goes between each Kling take and its trim once #3524 ships. Until it lands there is NO placeholder node on this board: a dead node is worse than none. If a reel is still under 200 WPM after it, add 1.08 to 1.1x speed on the take BEFORE the Voice Swap (the swap re-voices, so no chipmunk pitch).

## Room plate
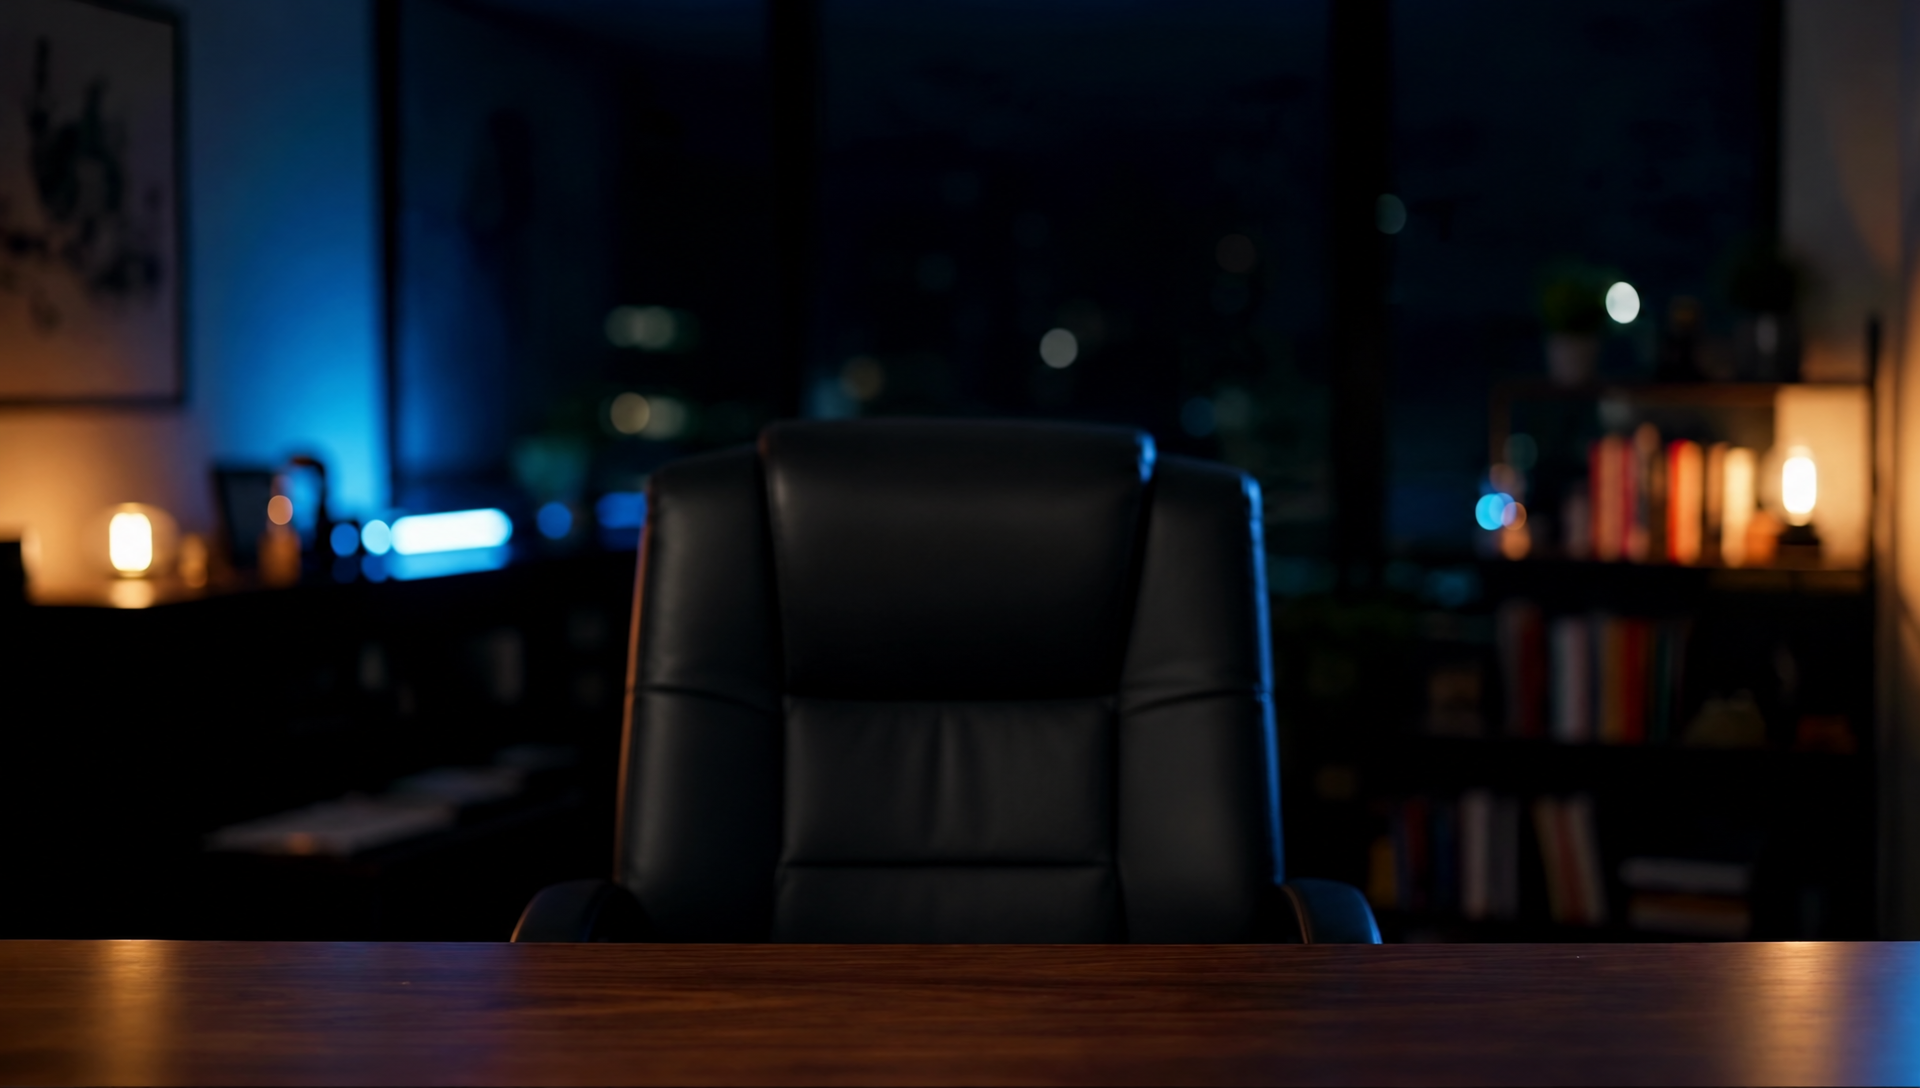
ROOM PLATE is pinned and reused while LOCKED PLATE v2 is unchanged. Only if the plate changes: run ROOM SOURCE (frame 0 of T1) -> ROOM PLATE REBUILD (paid GPT Image 2.5 edit), then pin the result into ROOM PLATE.
Inputs and what's baked in
Overridable inputs become sockets on the left of the node. Baked ones are served as outputs, so you get the author's asset without supplying your own.
- Not exposedTALKER PROMPT T1 · swap ONLY the quoted line + the emphasis word; keep start-frame, framing, delivery (falling statement ending, brisk pace) and realism wording; speaks in @Voice1input:text · ANY
- Overridable inputREF 1 · Michael real front (identity only, never mirrored)input:image · IMAGE
- Overridable inputREF 3 · Michael real 3/4 left (identity only)input:image · IMAGE
- Overridable inputSCRIPT LINE T1 · hook (the words of take T1; paste the same line into TALKER PROMPT T1)input:text · TEXT
- Not exposedPAPER texture (Oct 20 reel grain, multiply over every graphics beat)input:image · ANY
- Overridable inputSCRIPT LINE T2 · (the words of take T2; paste the same line into TALKER PROMPT T2)input:text · TEXT
- Not exposedTALKER PROMPT T2 · swap ONLY the quoted line + the emphasis word; keep start-frame, framing, delivery (falling statement ending, brisk pace) and realism wording; speaks in @Voice1input:text · ANY
- Overridable inputSCRIPT LINE T3 · (the words of take T3; paste the same line into TALKER PROMPT T3)input:text · TEXT
- Not exposedTALKER PROMPT T3 · swap ONLY the quoted line + the emphasis word; keep start-frame, framing, delivery (falling statement ending, brisk pace) and realism wording; speaks in @Voice1input:text · ANY
- Overridable inputSCRIPT LINE T4 · CTA (the words of take T4; paste the same line into TALKER PROMPT T4)input:text · TEXT
- Not exposedTALKER PROMPT T4 · swap ONLY the quoted line + the emphasis word; keep start-frame, framing, delivery (falling statement ending, brisk pace) and realism wording; speaks in @Voice1input:text · ANY
- Served as outputMUSIC BED · UNWIRED 10-31 (Michael: remove the music). House ElevenLabs bed, kept for reference onlyinput:image · IMAGE
- Not exposedSFX · whoosh (cuts)input:image · ANY
- Not exposedHOUSE · real Wireflow app icon (end card)input:image · ANY
- Not exposedEXAMPLE PROOF · Paris rooftop swap side-by-side (swap per episode)input:image · ANY
- Not exposedEXAMPLE PROOF · Ziggy swap compare (swap per episode)input:image · ANY
- Not exposedROOM PLATE PROMPT · remove Michael, keep the room exactlyinput:text · ANY
- Overridable inputLOCKED PLATE v2 · neutral relaxed mouth, lips closed (frame 0.29 s of the approved v5 T1 take, same room + framing) · T1 test start frameinput:image · IMAGE
- Overridable inputVOICE SAMPLE · Michael's REAL recorded voice, 27 s (61.2 to 88.2 s of take2, the 09-30 Blue Snowball recording his Michael v2 clone was trained on)input:image · IMAGE
- Not exposedPROOF · REAL UI · Kling 4 Voice Fix board (cmvw78gba0002l008zu8h9xio), whole boardinput:image · ANY
- Not exposedPROOF · VoiceStudio reel v3 frame (white graphics)input:image · ANY
- Not exposedPROOF · QC frame grid from the VoiceStudio reelinput:image · ANY
- Not exposedPROOF · VoiceStudio reel v5 frame (final)input:image · ANY
- Not exposedPROOF · VoiceStudio reel v1 frameinput:image · ANY
- Not exposedPROOF · VoiceStudio reel v2 frameinput:image · ANY
- Not exposedPROOF · Genjutsu SWAP reel clip (14.8k views, 636 comments)input:image · ANY
- Not exposedPROOF · VoiceStudio reel clip (10-31)input:image · ANY
- Not exposedPROOF · Halloween reel clip (10-31)input:image · ANY
- Not exposedEXAMPLE (10-30, swap per episode) · REAL OUTPUT · Kawarimi iso-color (depth inside the person, real room outside)input:image · ANY
- Not exposedEXAMPLE (10-30, swap per episode) · REAL OUTPUT · Kawarimi video-editor: the Raj swap with the original audioinput:image · ANY
- Not exposedEXAMPLE (10-30, swap per episode) · REAL OUTPUT · Wolf board: raw Kling 4.0 edit, no mask (the leak: Leo face, Michael beard)input:image · ANY
- Not exposedROOM PLATE · the shared empty room, pinned (reuse every episode while LOCKED PLATE v2 is unchanged)input:image · ANY
- Not exposedPROOF · VoiceStudio reel v3 frameinput:image · ANY
- Not exposedEXAMPLE (10-30, swap per episode) · REAL OUTPUT · Wolf v3: speaker-only mask + depth + Face Mesh, Kling 4.0 take, head pasted back (only the head is new)input:image · ANY
- Overridable inputSCRIPT LINE T5 · CTA (the words of take T5; paste the same line into TALKER PROMPT T5)input:text · TEXT
- Not exposedTALKER PROMPT T5 · swap ONLY the quoted line + the emphasis word; keep start-frame, framing, delivery (falling statement ending, brisk pace) and realism wording; speaks in @Voice1input:text · ANY
- Overridable inputSCRIPT LINE T6 · CTA (the words of take T6; paste the same line into TALKER PROMPT T6)input:text · TEXT
- Not exposedTALKER PROMPT T6 · swap ONLY the quoted line + the emphasis word; keep start-frame, framing, delivery (falling statement ending, brisk pace) and realism wording; speaks in @Voice1input:text · ANY
See it run
Real outputs from this Blueprint's nodes.
Ask Claude for your next ad.
Connect once. Ask any time.
- No credit card
- You keep the rights to what you make
- Cancel anytime